
Gemini 4 Argon ranks fifth of 73 on the legal benchmark Google cites as leading

Google says Gemini 4 Argon shows “similarly leading performance” on Harvey’s Legal Agent Benchmark, one of two outside evaluations it names in its Gemini 4 Argon announcement of September 30. That benchmark’s public leaderboard, run by Vals, ranks Argon fifth of 73 models at 19.58%, with four of Meta’s Muse Spark models above it.
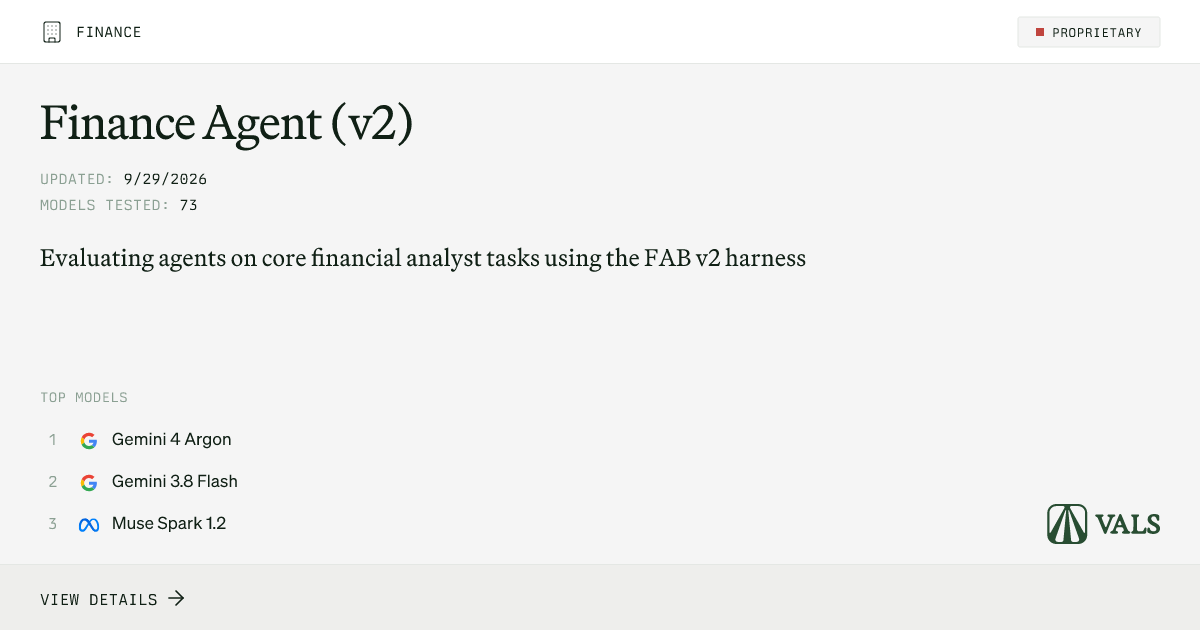
Vals’ card for Finance Agent v2, the other evaluation Google names, with Gemini 4 Argon listed first of 73 models. Image: Vals
Muse Spark 1.2 leads at 25.42%, followed by Muse Spark 1.3 Max at 23.75%, Muse Spark 1.3 at 22.92% and Muse Spark 1.1 at 20.00%, according to Vals, whose page was updated on September 30, the day Google published. Argon’s own Vals model page gives the same result, 19.58% with a standard error of 3.31.
Google compared Argon with three rivals, and beat all three
Google’s evaluation document for Argon says the Harvey results are “sourced from Vals AI”, the same operator that publishes the leaderboard, and runs Argon against GPT-6 Astra, Claude Fable 5.1 and Claude Opus 5.5. No Meta model appears in it.
Against those three, Google puts Argon at 19.6% on Harvey’s benchmark, Claude Fable 5.1 at 6.7%, GPT-6 Astra at 5.4% and Claude Opus 5.5 at 3.8%. Vals publishes the same three rival figures, so Google’s phrase holds comfortably against the field it picked, and the four models ahead of Argon on the public board are not in that field.
Argon does lead the other benchmark in the same sentence
The other evaluation Google names is Vals Finance Agent v2, and there Argon is first of 73 at 65.40%, ahead of Gemini 3.8 Flash at 61.44%.
Argon’s record across Vals’ other boards splits the same way. It is first on the Vals Index at 68.90% of 41 models and ties for first on IOI at 100.00%, second on Vibe Code Bench at 91.91% and on Code Migration at 68.17%, then fifth of 54 on ProgramBench at 2.50% and seventh of eight on CUA-bench at 4.83%.
The Harvey runs were not set to a common effort level
Vals records Argon’s Harvey run at a reasoning effort of “high”, temperature 1.0 and a 262,144-token output cap. It records Muse Spark 1.1, 1.2 and 1.3 at “xhigh” and Muse Spark 1.3 Max at “max”, so the ranking does not hold that setting constant across the models in it.
Everything on this board scores low. Vals describes the benchmark as testing “an agent’s ability to complete legal work using documents, spreadsheets, presentations, and file-system tools”, and 25.42% is what the top of it looks like.
Vals also publishes a criteria pass rate, which counts individual requirements met rather than tasks finished, and those run far higher. Argon’s is 94.04%, behind Muse Spark 1.3 Max on 94.74% and Muse Spark 1.2 on 94.52%.
Legal work is a market every large lab is chasing. OpenAI opened Astra for Law, which searches 230 million legal URLs, to invited firms in September.
Argon itself is going out only to trusted cyber defenders for now, so Vals’ runs and Google’s own document are the only numbers anyone has on it.

