
GPT-6 Astra's Ultrafast tier costs $300 per million output tokens, six times standard
OpenAI has added an Ultrafast service tier for GPT-6 Astra, and on prompts of 272,000 input tokens or fewer it charges $300 per 1M output tokens where the standard tier charges $50. Input runs at $60 per 1M tokens against $10 on standard, cached input at $6 against $1 and cache writes at $75 against $12.50, which works out at six times the standard rate on every one of the four figures.
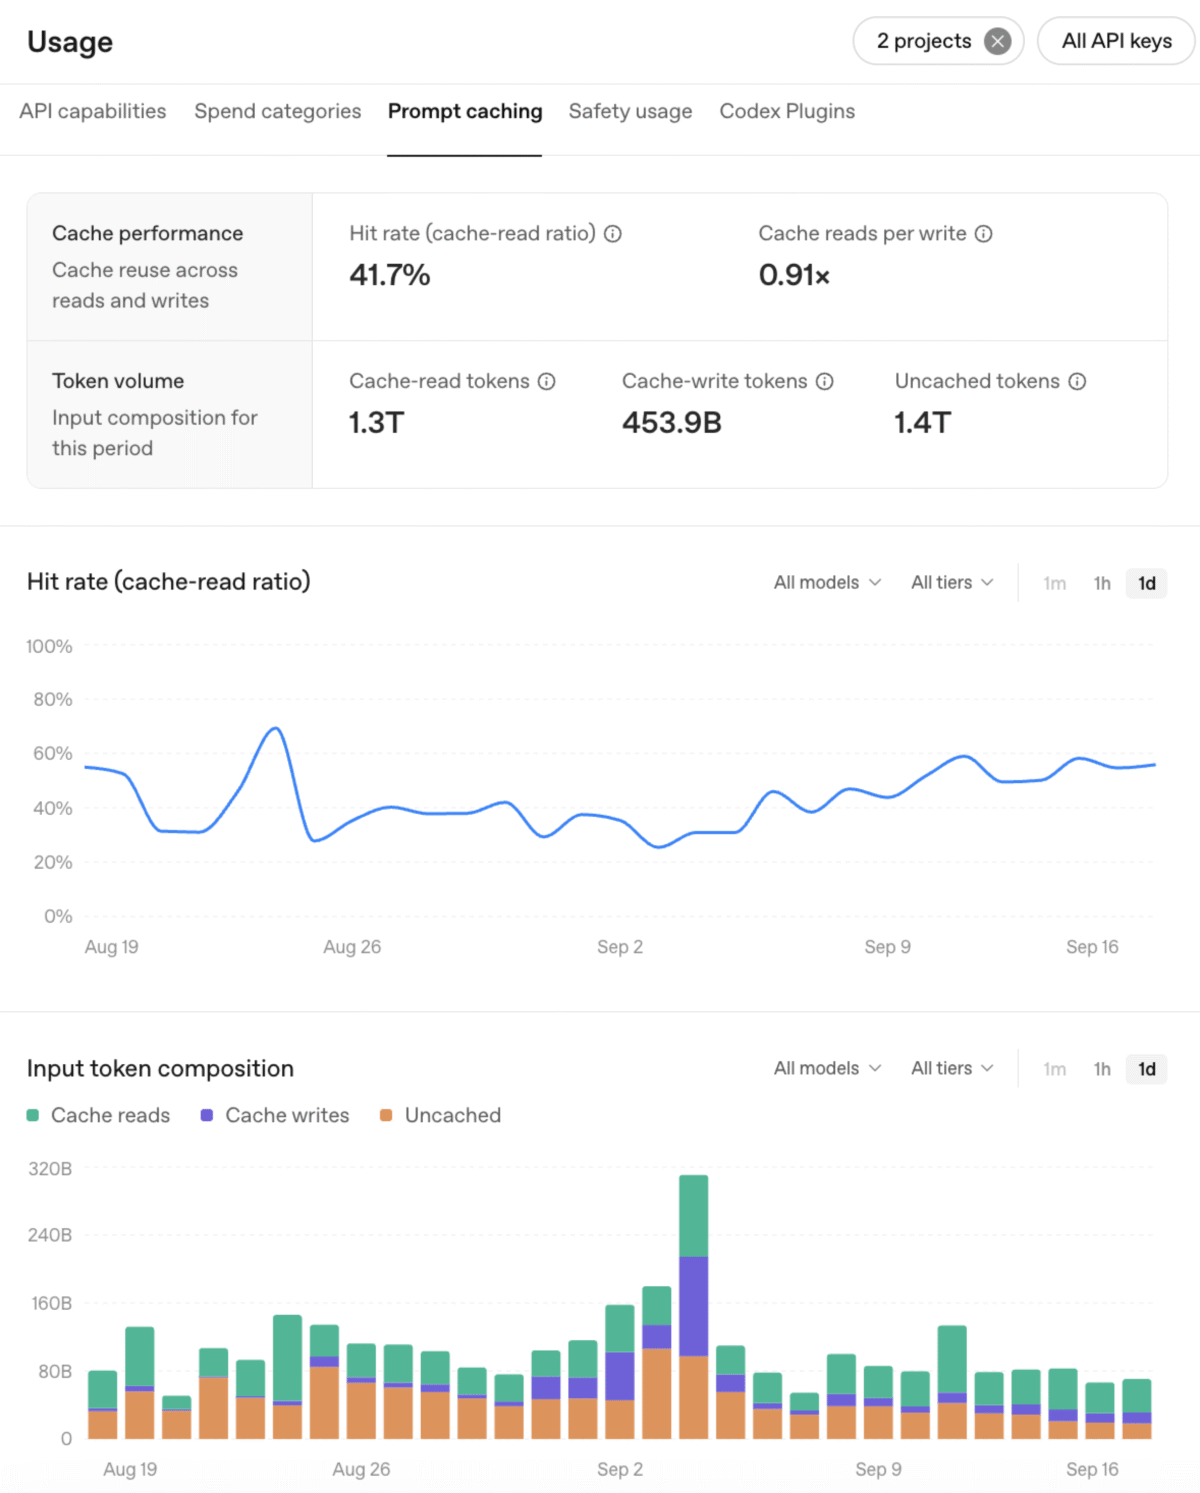
OpenAI's usage dashboard splits input tokens into cache reads, cache writes and uncached tokens, the three lines Ultrafast charges separately at $6, $75 and $60 per 1M tokens. Image: OpenAI
Developers choose the tier per request rather than buying it as a plan, by sending the model gpt-6-astra with service_tier set to ultrafast in the Responses API. OpenAI's changelog entry of September 29 says the mode is "available to API customers, subject to rate limits, with global processing and US data residency".
Ultrafast will not run on an EU residency endpoint
"Ultrafast supports US data residency and global processing only. It does not support EU or other non-US regional processing endpoints," OpenAI's guide to the tier says. A European customer can still send Ultrafast requests through global processing, but cannot keep the inference inside an EU regional endpoint while doing it.
That is a harder limit than it first looks for anyone whose contracts specify where inference happens. OpenAI charges a 10% uplift on regional processing endpoints for models released on or after March 5, 2026, so residency costs extra on the tiers that offer it at all.
The rate limits start deliberately low
Default Ultrafast token rate limits for GPT-6 Astra are 500,000 tokens per minute for API usage tiers 1 to 3, 1M tokens per minute for tier 4 and 5M for tier 5. OpenAI says the mode "is currently available to all API users at low rate limits", and tells organisations that work with an OpenAI account team to ask them for higher ones.
The same route covers preview access to Ultrafast for GPT-5.6 Sol, which is not generally available on the tier. GPT-6 Astra is the only model with published Ultrafast prices.
Long prompts carry the same multiple
Above 272,000 input tokens, Ultrafast costs $120 input, $12 cached input, $150 cache writes and $450 output per 1M tokens, against $20, $2, $25 and $75 on standard. Six times holds across the long-context rates as well as the short ones.
Fast mode, the tier renamed from Priority processing on July 30, 2026, sits in between at $20 input, $2 cached input, $25 cache writes and $100 output per 1M tokens on short context. Ultrafast is exactly three times those rates, and six times standard, on all four of them in OpenAI's published pricing.
For scale, GPT-6.1 Sol, which OpenAI released the same day, costs $2 input and $10 output per 1M tokens on standard short-context pricing. Ultrafast GPT-6 Astra output is 30 times that. Cached input is the one line where the gap narrows in absolute terms, and OpenAI's cache discounts still apply, at $6 per 1M tokens instead of $60.
OpenAI recommends a persistent connection
OpenAI tells developers to use WebSockets with the tier, "especially for agentic applications that make many tool calls in quick succession", and warns that "without a persistent connection, network overhead can reduce the latency gains". Plain HTTP works too, through the same SDKs.
The speed figures come with a surface attached
Neither the changelog nor the guide puts a number on the speed, and both describe the benefit only as reducing "the time between generated output tokens". The figures are in OpenAI's DevDay 2026 recap, which says Ultrafast "offers up to 8× faster token generation (300 tokens per second) in Codex and up to 6x in the API". Those are claims for the tier rather than for GPT-6 Astra by name, and the two halves are not interchangeable: 300 tokens per second is the Codex number, and for the API OpenAI gives a multiple and no throughput figure at all.
GPT-6 Astra is the model running on Ultrafast in the API, and in ChatGPT Work and Codex on Pro 500 and Enterprise plans, the same recap says, with GPT-6.1 Sol Ultrafast "coming soon". So a developer paying $300 per 1M output tokens in the API is buying up to six times the speed for exactly six times the price.

