
Google's new 4B Gemma model cuts speaker-labelling errors on all four benchmarks, two barely

A 4B-parameter model published under Google's Hugging Face organisation on October 4 reports lower speaker-labelling error on all four of the standard diarisation test sets, with the improvements marked as statistically significant at p < 0.0001. Google is blunt about what it has released: "This is not an officially supported Google product", the model card for DiarizationLM-Gemma-4-E4B-v1 says in bold, so this is code and weights rather than a product launch.
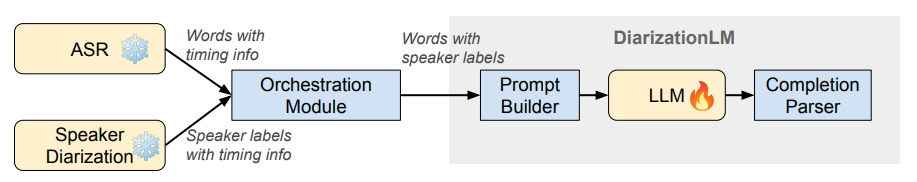
DiarizationLM sits after the recogniser and the diarisation system, correcting what they produce rather than replacing either. Image: Google
Diarisation is the part of transcription that decides who spoke. Speech recognition writes down the words; diarisation attaches a speaker to each of them, and when it fails a four-person meeting comes back as one long monologue or swaps two people in the middle of a sentence.
DiarizationLM does not do either job from scratch. It is a framework that takes the output of a recogniser and a diarisation system and corrects it afterwards, which is why its results are quoted against a baseline rather than as absolute accuracy.
The gains are large on phone calls and small in meetings
The metric is word diarisation error rate, the share of words handed to the wrong speaker. Against a USM and turn-to-diarize baseline, Google reports WDER falling from 5.32% to 2.99% on Fisher English, from 7.74% to 4.92% on Callhome American English, from 14.70% to 14.10% on the ICSI meeting corpus and from 15.68% to 14.89% on AMI.
Two of those are worth under a percentage point. The paired changes are -2.33 and -2.82 points on the two telephone corpora and -0.60 and -0.79 points on the two meeting corpora, and significance at p < 0.0001 says the difference is real, not that it is large. The ICSI test split is three meetings and the AMI one is 16, which is a thin basis for a claim about meetings in general.
Half the parameters of the model it improves on
The comparison Google leans on is against google/DiarizationLM-8b-Fisher-v2, built on Llama 3 8B and scored on the same baseline. On Fisher the new 4B model reports 2.99% WDER against the 8B model's 3.28%, and on Callhome 4.92% against 6.66%, "despite having half the parameter count (4B vs. 8B)". No 8B figure is published for ICSI or AMI, so the size comparison covers telephone speech only.
Google credits the training recipe rather than the base model, naming Locality-Preserving Oracle Supervision, which it describes as teaching the model to correct turn boundaries and short backchannels while holding speaker identity steady across long monologues. Training ran for 10,000 steps with a LoRA adapter at rank 256 on eight Google Cloud TPU v5p chips.
Apache 2.0, and no downloads logged yet
The licence is Apache 2.0. The merged 16-bit weights run to about 16.0 GB, and two 4-bit GGUF builds at roughly 5.30 GB and 5.15 GB are published for llama.cpp and Ollama. At 00:00 UTC on October 5 the Hugging Face API reported zero downloads and nine likes for the repository.
No latency figure is published, and no on-device measurement, so nothing here says what it would do on a phone or in a pair of glasses. For comparison on the same task from a different direction, Nvidia released a 100M-parameter diarisation model on September 28 that does the labelling itself instead of correcting someone else's. The underlying DiarizationLM paper dates to Interspeech 2024, so the framework is older than the weights.

